DeepSeek V4.1 Flash is one of the cheapest strong models you can call today. Off-peak it costs $0.15 / $0.60 per 1M tokens, cache hits are almost free, and the 1M context suits long agent runs.
AI Agents · Tool review
DeepSeek V4.1 Flash: API Pricing & Free Use
 TechPilot.ai review team Hands-on testing, one published method
- Last updated
- How we test
Summary
Pros and cons
What we like
- Very cheap $0.15 input and $0.60 output per 1M tokens off-peak.
- Open weights MIT licence on Hugging Face.
- Long context 1M tokens with up to 384K output.
- Native vision Reads images and text in one model.
- Strong agent scores Matches pricier models on several of DeepSeek's coding tests.
What could be better
- Peak surcharge Weekday peak hours double every rate.
- Huge to self-host Not practical on consumer GPUs.
- Self-reported benchmarks Scores come from DeepSeek's model card.
- No V4.1 Pro yet Pro requests route to Flash for now.
Key features
- 1M context: Up to 384K output tokens on the API.
- Thinking modes: Thinking by default, non-thinking for fast replies.
- Native multimodal: Images and text in the same model.
- Two API formats: OpenAI-compatible and Anthropic-compatible endpoints.
- Off-peak pricing: Half price outside weekday peak hours.
- MIT open weights: Self-host with vLLM or SGLang.
Screenshots
Full review
Independent and reader-supported. Some links may earn us a commission; it never changes our scores. Editorial policy
DeepSeek V4.1 Flash costs $0.15 per 1M input tokens and $0.60 output off-peak on the DeepSeek API. See peak rates, free options, open weights and specs.
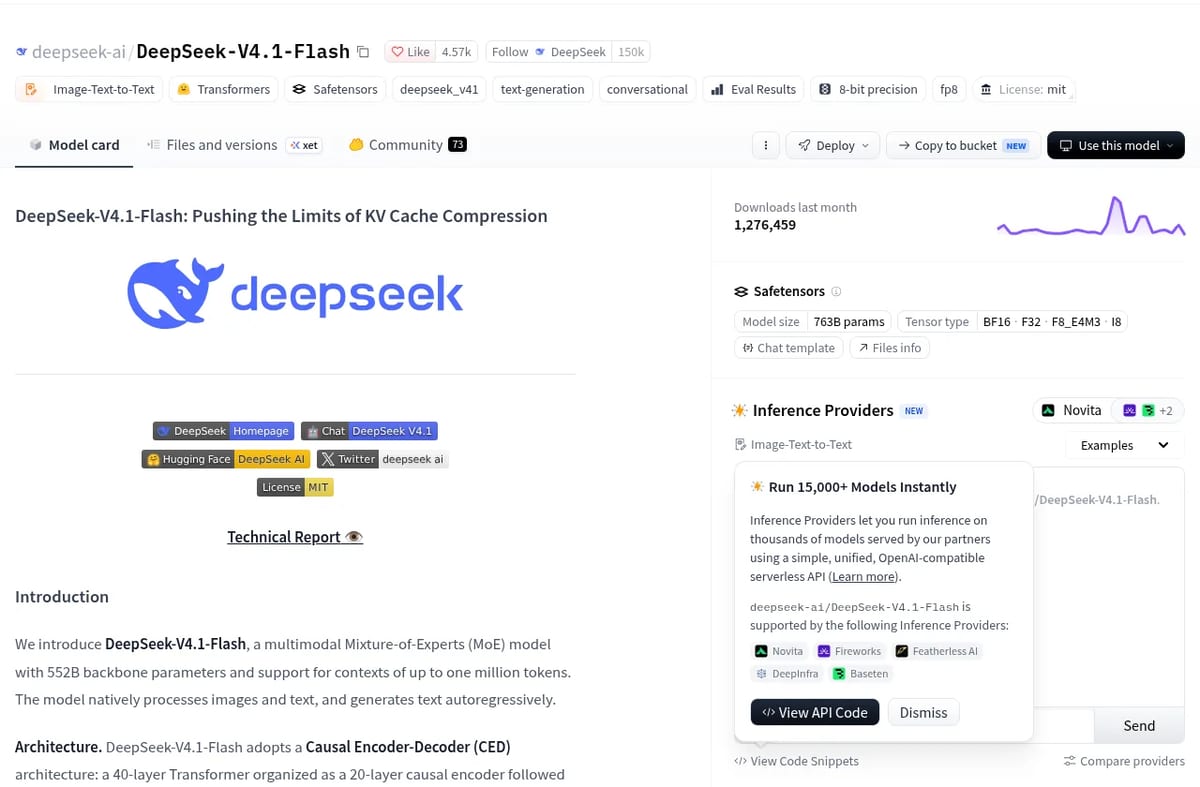
DeepSeek released DeepSeek-V4.1-Flash on September 10, 2026, and it is now the default model on the DeepSeek API. It is the first and smallest model in DeepSeek’s V4.1 family, with native image understanding, a 1M-token context window and open weights under the MIT licence. DeepSeek is retiring V4-Flash and V4-Pro in its favour. This page covers the verified API prices, the free ways to use it and what changed from V4.
What is DeepSeek V4.1 Flash?
V4.1 Flash is a mixture-of-experts model with a 552B-parameter backbone. It uses a new causal encoder-decoder design that activates only 8B parameters per token when reading input and 16B when generating output. According to the Hugging Face model card, that split is what makes it cheap for input-heavy agent work. It reads images and text natively and supports both thinking (the default) and non-thinking modes.
- Context: 1M tokens, with up to 384K output tokens on the API.
- Smaller cache: DeepSeek says its KV cache needs about 1/4 of the GPU memory and 1/8 of the SSD storage of the previous generation, which matters because cache hits drive much of an agent’s cost.
- Reasoning control: the model card describes a reasoning-effort setting from 1 to 100 that trades cost for accuracy.
- API features: JSON output, tool calls, the Responses API, an Anthropic-format endpoint and vision.
DeepSeek V4.1: Flash now, Pro later
If you searched for “DeepSeek V4.1”, Flash is the only V4.1 model out so far. DeepSeek’s launch note says that from September 14, 2026, all deepseek-v4-pro requests route to V4.1 Flash at Flash prices, “until V4.1-Pro launches.” DeepSeek has not given a date for V4.1 Pro. The legacy model names deepseek-v4-flash and deepseek-v4-flash-vision-exp also route to V4.1 Flash.
DeepSeek V4.1 Flash Pricing (2026)
DeepSeek bills per token from a prepaid balance, with off-peak rates at half the peak rates. We checked the DeepSeek API pricing page on October 17, 2026. Prices are per 1M tokens for the deepseek-flash model:
| Token type | Off-peak | Peak |
|---|---|---|
| Input, cache hit | $0.003 | $0.006 |
| Input, cache miss | $0.15 | $0.30 |
| Output | $0.60 | $1.20 |
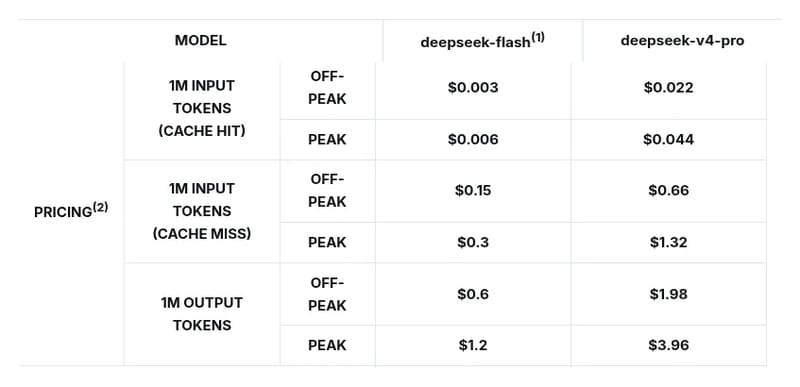
Peak hours are 01:00 to 04:00 and 06:00 to 10:00 UTC, Monday to Friday, excluding Chinese public holidays. In Vietnam time (UTC+7), that is 8:00 to 11:00 and 13:00 to 17:00 on weekdays. Every other hour, including weekends, is off-peak, so batch jobs that can wait should run then. DeepSeek’s separate Search and Fetch APIs cost $0.75 per 1,000 successful requests each.
Is DeepSeek V4.1 Flash free?
The API is not free, but there are three ways to use V4.1 Flash without paying DeepSeek per token:
- Open weights: the full model is on Hugging Face under the MIT licence, with vLLM, SGLang and Docker instructions. The weights are large (Hugging Face lists 763B parameters), so this is a data-center option, not a laptop one. See our best local AI models for models that fit consumer hardware.
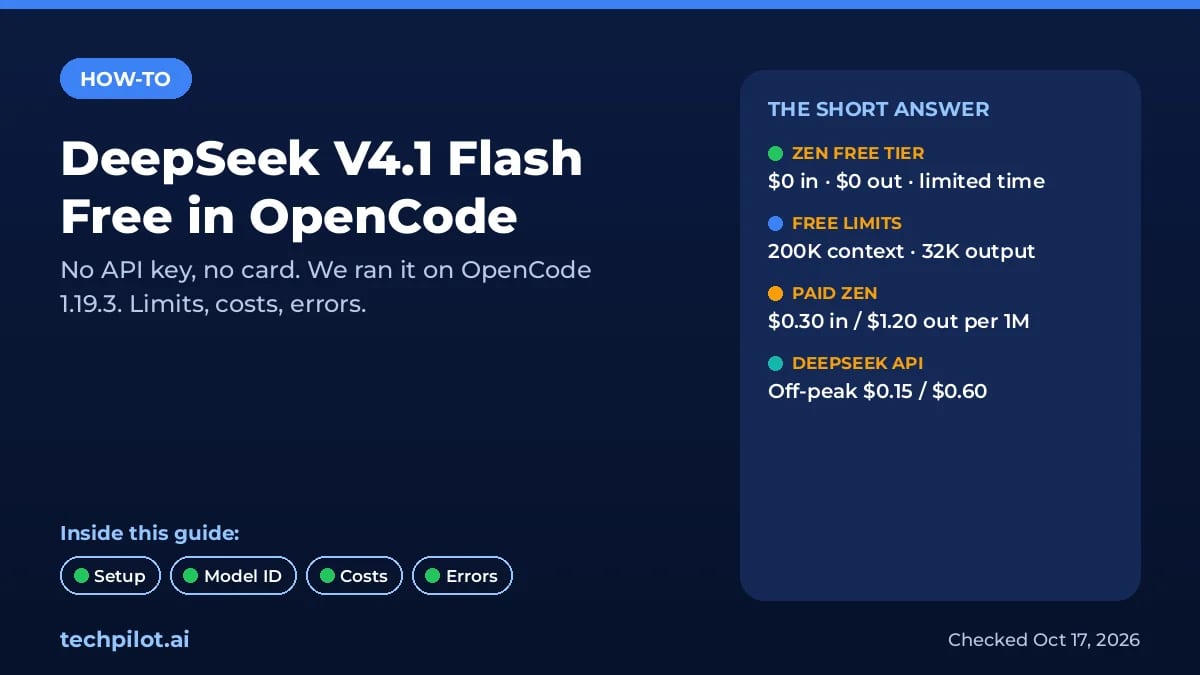
- OpenCode Zen: OpenCode lists a “DeepSeek V4.1 Flash Free” model (deepseek-v4.1-flash-free) that is free for a limited time. OpenCode says its provider keeps no data and doesn’t train on it. The paid deepseek-v4.1-flash model on Zen costs $0.30 input and $1.20 output per 1M tokens.
- DeepSeek’s own chat: the DeepSeek website and app are free to use, and the homepage announces V4.1 Flash as the official release. DeepSeek doesn’t publish a separate model table for the chat app, though.
How to use the DeepSeek V4.1 Flash API
- Top up your balance on the DeepSeek platform and create an API key.
- Set the model to deepseek-flash with base URL https://api.deepseek.com (OpenAI format) or https://api.deepseek.com/anthropic (Anthropic format).
- Pick a mode: thinking is on by default. Switch to non-thinking for fast, cheap replies.
- Use it in coding agents: DeepSeek’s docs cover Claude Code, Codex, OpenCode and its own DeepSeek Harness.
- Schedule big jobs off-peak to pay half price.
Benchmarks (DeepSeek’s own numbers)
DeepSeek’s model card compares V4.1 Flash at maximum reasoning effort with frontier models. These are self-reported scores:
| Benchmark | V4.1 Flash | Opus-5.0 | GPT-5.6 Sol | V4-Pro |
|---|---|---|---|---|
| Terminal-Bench 2.1 | 90.6 | 89.1 | 88.8 | 87.9 |
| DeepSWE v1.1 | 74.2 | 74.0 | 73.0 | 62.7 |
| AutomationBench | 54.8 | 50.3 | 45.8 | 43.2 |
| GPQA Diamond | 90.9 | 93.4 | 94.1 | 92.4 |
| Terminal-Bench 3.0 | 30.0 | 43.3 | 34.4 | 11.8 |
The pattern is clear: V4.1 Flash matches or beats much more expensive models on several agent and coding tests, and clearly beats DeepSeek’s own V4-Pro. It still trails the top closed models on the hardest new tests and on GPQA. For how we weigh launch scores, see our best AI model guide. Paper Instruments also used V4.1 Flash as a comparison model for Ultramarine 1 Flash.
Limitations
- Peak pricing: weekday peak hours double every rate.
- Hard to self-host: open weights, but far too large for consumer GPUs.
- Vendor benchmarks: the scores above are DeepSeek’s own.
- Moving model names: V4 models are retired and route to V4.1 Flash, so check which model you’re actually billed for.
- Data location: DeepSeek is a Chinese company. Some teams prefer the open weights or a third-party host for that reason. Our open vs closed AI guide covers the trade-offs.
TechPilot.ai’s Verdict on DeepSeek V4.1 Flash
DeepSeek V4.1 Flash is one of the cheapest strong models you can call today. Off-peak it costs $0.15 / $0.60 per 1M tokens, cache hits are almost free, and the 1M context suits long agent runs.
Run heavy jobs off-peak, test it on your own tasks rather than trusting the vendor charts, and use the MIT weights or a third-party host if data location matters to you.
DeepSeek V4.1 Flash FAQ
Is DeepSeek V4.1 Flash free?
The DeepSeek API is paid, but the weights are free under the MIT licence on Hugging Face, OpenCode Zen offers a limited-time free version (deepseek-v4.1-flash-free), and DeepSeek’s own chat website and app are free to use.
•
How much does DeepSeek V4.1 Flash cost?
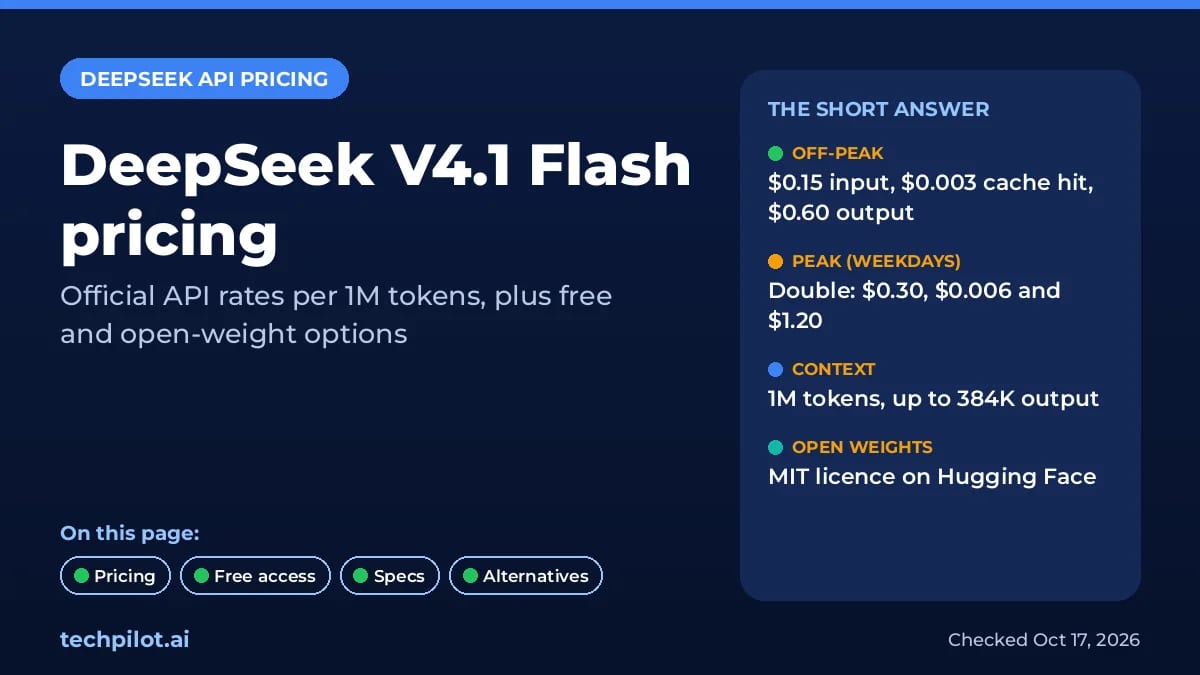
On the DeepSeek API (checked October 17, 2026), off-peak rates are $0.15 per 1M input tokens on a cache miss, $0.003 on a cache hit and $0.60 per 1M output tokens. Weekday peak hours cost double: $0.30, $0.006 and $1.20.
•
What is the context length of DeepSeek V4.1 Flash?
1M tokens, with up to 384K output tokens on the DeepSeek API. The model also reads images natively.
•
Is DeepSeek V4.1 Flash open source?
Yes, it is open-weight. The weights and repository are released under the MIT licence on Hugging Face as deepseek-ai/DeepSeek-V4.1-Flash. The model launched on September 10, 2026.
•
What model name do I use for DeepSeek V4.1 Flash?
Use deepseek-flash with base URL https://api.deepseek.com. The old names deepseek-v4-flash and deepseek-v4-flash-vision-exp still work and are served by V4.1 Flash.
ElevenLabs
AI Agents
ElevenLabs is the AI voice platform (elevenlabs.io) most creators use as the quality benchmark: expressive text to speech with the new…
Hello Haven
AI Agents
Hello Haven is one of the most accessible personal agents so far: you can literally call or text it, and its memory carries across every…
OpenAI SDK
AI Agents
I’ve been tracking the development of AI agents for years, and the move from command-line plugins to fully integrated graphical experiences…
Web development & Coding  Eimantas Kazėnas · 8 min read
What Are Tokens in AI? A Simple Guide (2026)
What are tokens in AI? Tokens are the small chunks of text a model reads and writes. See a tokenizer example, context windows and real costs per 1M…
Eimantas Kazėnas · 8 min read
News Eimantas Kazėnas · 6 min read
DeepSeek V4.1 Flash Free in OpenCode: How-To
DeepSeek V4.1 Flash is free in OpenCode for now: no API key, no card. We tested it on OpenCode 1.19.3. Setup steps, the model ID, limits, costs and…
Eimantas Kazėnas · 6 min read